Holon Research, Inc
Infrastructure for private intelligence.
Reserve beta unit
From $20,000 · 8 units left
Infrastructure for private intelligence.
From $20,000 · 8 units left
Up to 3x the performance of standard engines.
No cloud, no telemetry.
Serve your whole team on your LAN.
Your weights, your rules.
Accounts, queues, serving on day one.
Traces become training data.
Outlet to first token.
Up to 3x the performance of standard engines.
No cloud, no telemetry.
Serve your whole team on your LAN.
Your weights, your rules.
Accounts, queues, serving on day one.
Traces become training data.
Outlet to first token.
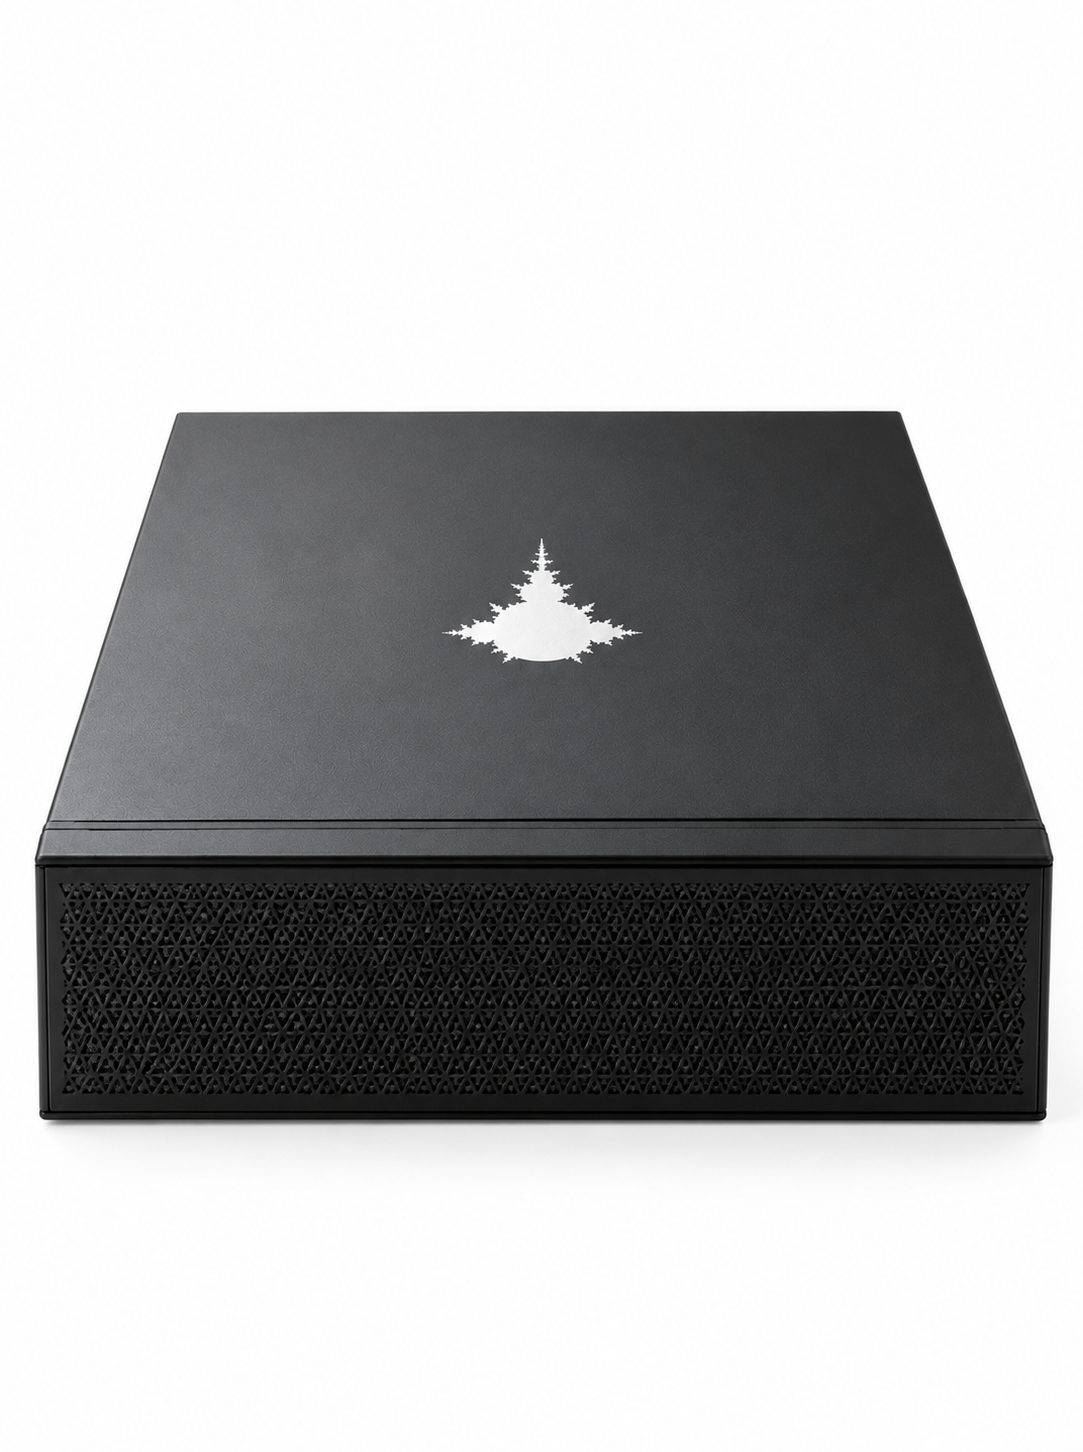
Custom C++/HIP engine designed for 4×R9700. Squeezes every drop of compute.
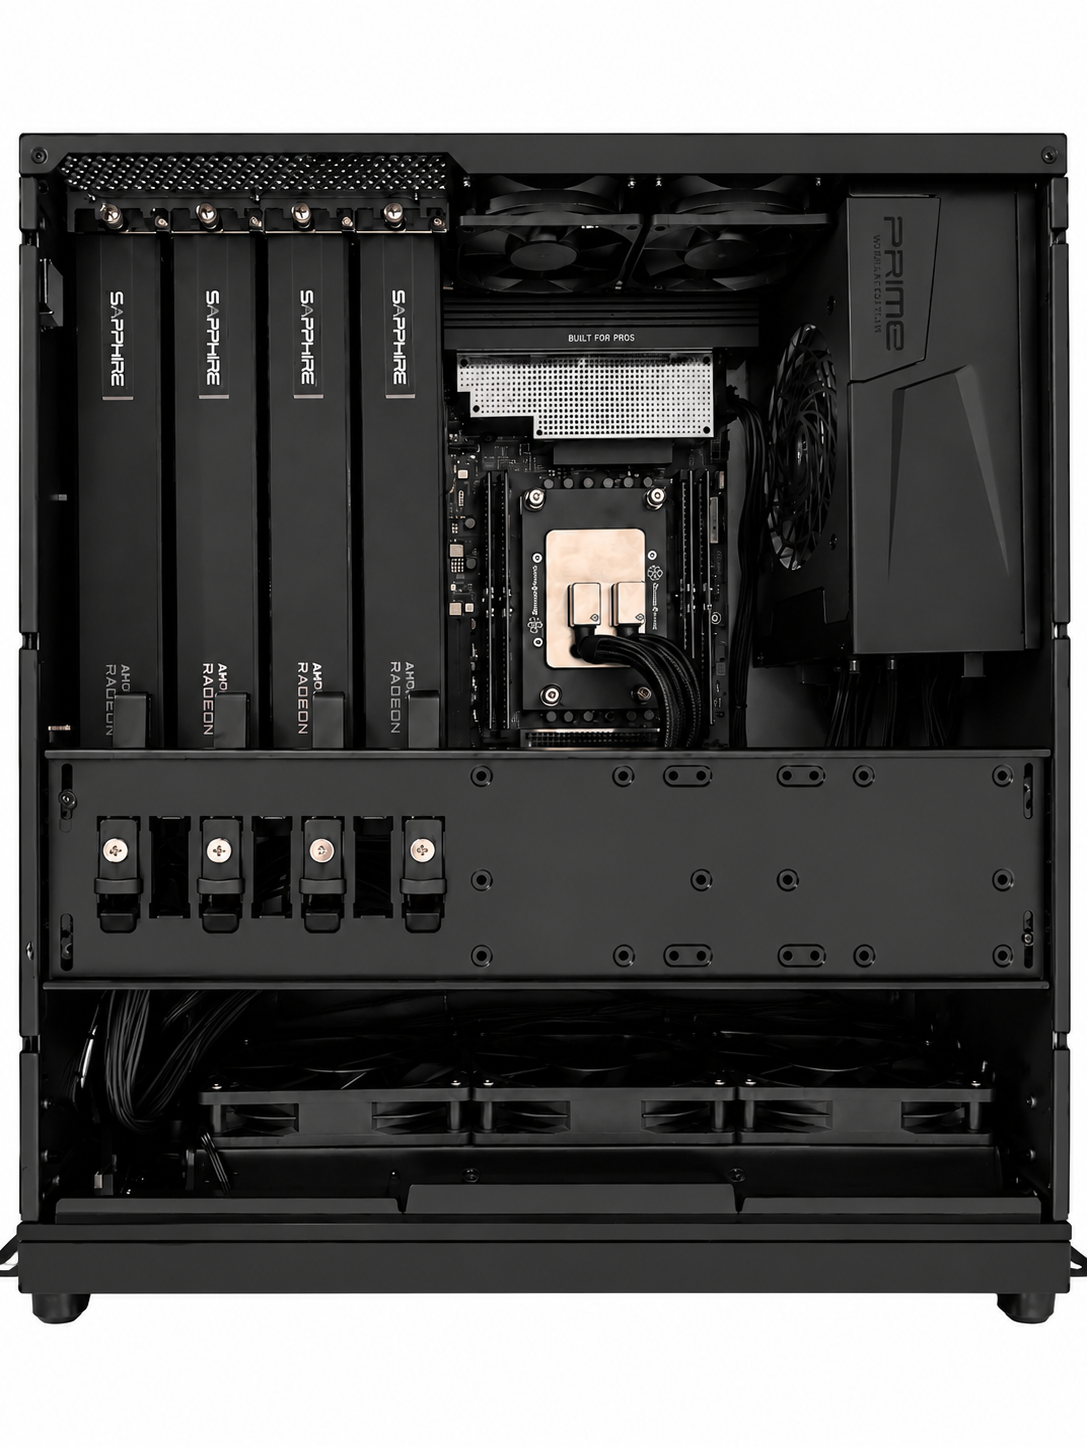
Based on Qwen3.8-27B MXFP4, 90/10 input/output split, 99% cache hit rate, and 60% utilization over 30 days.
| Model profile | Quant | KV type | Users | Prefill | Peak aggregate decode at 4K | Context window |
|---|---|---|---|---|---|---|
| Qwen3.8-27B MXFP4 | MXFP4 | BF16 | 16 | 9,830.96 tok/s | 1,426.02 tok/s | 131,072 tokens |
| Qwen3.8 Next Flash Int4/FP8 | Int4/FP8 | BF16 | 16 | 7,243 tok/s | 849 tok/s | 131,072 tokens |
| Qwen3.8-27B FP8 | FP8 | BF16 | 8 | 4,453 tok/s | 322.26 tok/s | 139,264 tokens |
| DeepSeek V4.0 Flash 0731 | native | FP8 | 4 | 2,268 tok/s | 105.99 tok/s | 262,144 tokens |
Supported models
Uncensored / Abliterated
Need to deploy a custom model instead?
Reach outPlug into any standard 15-amp outlet, assign IP, serve inference
Supports: pplx-embed-context (BF16), Nemotron-3.5-Embed-1B-BF16
Use self-hosted tools, or BYO
Beta price
8 units left in the beta batch · 2 of 10 booked
Ships week of Dec 1st ·
Try a unit before you buy